LogoDream Filler
ENTERPRISE AI ENGINEERING

Enterprise LLM Support & Maintenance

Open-source AI. Enterprise-ready engineering.

Build, deploy, optimise and maintain enterprise-ready Large Language Models with complete control over your data, models and infrastructure.

From model selection and fine-tuning to RAG, private deployment, security and continuous maintenance, Dream Filler provides end-to-end LLM engineering and lifecycle support.

  • Tuned to your data
  • Deployed on your infrastructure
  • Supported throughout the lifecycle
Open Models. Private Infrastructure. Continuous Engineering.•Powered by LLM-MONK
Reference Architecture
Tap Layer to Inspect
Central LLM Engineering Architecture
Controlled Boundary

Unified control plane combining RAG pipelines, LLM/MCP gateways, guardrails, and lifecycle evaluation.

Dream Filler Engineering × Powered by LLM-MONK

Architectural Control

Your Models. Your Data. Your Infrastructure.

Enterprise AI should work around your business requirements, not force your business to adapt to restrictive AI infrastructure.

Dream Filler helps organisations implement flexible LLM environments with control over data ownership, model selection, infrastructure and operational costs.

Data Ownership

Keep business knowledge and sensitive information within controlled environments. Training datasets, embeddings, prompts, and inference logs remain strictly inside your organisational boundaries.

  • Zero mandatory reliance on third-party model APIs
  • Tenant-isolated vector stores and document pipelines
  • Clear data lineage across ingestion, retrieval, and serving

Infrastructure Flexibility

Deploy LLMs on-premise, in private clouds or within suitable cloud environments. Architect workloads around existing hardware, data residency policies, and budget realities.

  • Portable containerised serving across cloud and bare metal
  • Support for VPC-isolated and air-gapped topologies
  • Model portability across open-weight architectures

Continuous Engineering

Ensure your LLM ecosystem remains optimised, secure and production-ready. Move beyond initial prototypes with structured evaluations, release governance, and ongoing engineering.

  • Proactive drift monitoring and regression test suites
  • Controlled model updates, patching, and version pinning
  • Predictable operational handoffs and runbook discipline
Complete Service Portfolio

Everything Your Enterprise Needs to Run LLMs in Production

From initial architecture to ongoing production support, our services cover the complete lifecycle of enterprise LLM solutions.

01/Model & Knowledge Engineering

01. Model Customisation & Fine-Tuning

Adapt open-weight foundation models to your domain terminology, structured output schemas, and proprietary workflows so models perform reliably on specialised enterprise tasks.

Core Capabilities

  • Full fine-tuning
  • Domain tuning
  • Task tuning
  • LoRA & QLoRA
  • Adapter management
02/Model & Knowledge Engineering

02. RAG & Enterprise Knowledge Management

Ground model responses in verified internal documentation, SOPs, and databases with traceable citations and permission-aware retrieval pipelines.

Core Capabilities

  • Data ingestion & chunking
  • Vector databases
  • Semantic & hybrid search
  • Reranking pipelines
  • Enterprise RAG implementation
03/Model & Knowledge Engineering

03. Model Selection & Evaluation

Make evidence-based model choices by evaluating open-weight candidates against your actual business prompts, accuracy bars, latency envelopes, and compute budgets.

Core Capabilities

  • Model benchmarking
  • Task evaluations
  • Accuracy assessment
  • Model comparison
  • Cost-quality analysis
04/Deployment & Inference

04. Enterprise LLM Deployment

Deploy production model serving stacks inside infrastructure you control—built for repeatability, isolation, and seamless integration with enterprise networking.

Core Capabilities

  • On-premise deployment
  • Private cloud environments
  • Air-gapped environments
  • Containerisation
  • Production model serving
05/Deployment & Inference

05. Hardware Optimisation & Inference Engineering

Extract dependable throughput and predictable latency from your GPU and CPU footprint through careful quantisation, memory planning, and serving engine tuning.

Core Capabilities

  • Model quantisation
  • Continuous batching
  • GPU sizing & placement
  • Memory optimisation
  • Inference performance & resource management
06/Gateways, Agents & Security

06. LLM Gateway, API & Intelligent Routing

Standardise how internal applications consume models through a unified control plane for routing, fallbacks, rate governance, and departmental cost visibility.

Core Capabilities

  • Unified APIs
  • Multi-model routing
  • Fallback mechanisms
  • Request management
  • API governance & cost tracking
07/Gateways, Agents & Security

07. MCP Gateway & AI Agent Integration

Connect LLMs safely to enterprise systems, APIs, and databases via Model Context Protocol (MCP) servers with governed tool registries and role-based permissions.

Core Capabilities

  • MCP server development
  • Gateway implementation
  • Skills registry
  • Access control
  • Tool orchestration & enterprise system integration
08/Operations, Lifecycle & Enablement

08. LLM Maintenance & Production Support

Keep production AI services reliable day-to-day with structured monitoring, incident handling, dependency updates, and ongoing engineering support.

Core Capabilities

  • Model monitoring
  • Incident management
  • SLA-based support
  • Engine & runtime upgrades
  • Troubleshooting & ongoing optimisation
09/Operations, Lifecycle & Enablement

09. Continuous Evaluation & Risk Management

Maintain output reliability over time by detecting quality drift early and validating every prompt, retrieval, or model change against regression benchmarks.

Core Capabilities

  • Model drift detection
  • Regression testing
  • Quality monitoring
  • Risk assessments
  • Continuous improvement
10/Operations, Lifecycle & Enablement

10. Long-Term Model Support

Protect regulated and mission-critical workloads from unexpected breaking changes through version pinning, hardened builds, and disciplined release governance.

Core Capabilities

  • Stable builds
  • Security fixes
  • Version pinning
  • Release management
  • Compatibility management & documentation
11/Operations, Lifecycle & Enablement

11. Model Migration & Modernisation

Transition smoothly from proprietary external APIs or aging AI implementations to modern open-weight architectures with parity testing and zero workflow disruption.

Core Capabilities

  • Model deprecation planning
  • Upgrade paths
  • Parity testing
  • Migration execution
  • Legacy AI modernisation
12/Gateways, Agents & Security

12. LLM Guardrails & Enterprise Security

Enforce policy boundaries across prompts, retrieved context, tool invocations, and model responses to mitigate prompt injection and sensitive data exposure.

Core Capabilities

  • Input/output filtering
  • Prompt injection protection
  • Data leakage prevention
  • Access management
  • Audit logging & usage governance
13/Operations, Lifecycle & Enablement

13. Enterprise AI Enablement

Equip your internal engineering, platform, and product teams with the documentation, workshops, and operational runbooks required to own LLM platforms confidently.

Core Capabilities

  • Technical training
  • Implementation workshops
  • Operational runbooks
  • Knowledge transfer
  • Architecture consulting & technical handover
14/Gateways, Agents & Security

14. Custom LLM Engineering

Build bespoke AI workflows, multi-step document pipelines, and application integrations tailored around your organisation’s operational processes and software stack.

Core Capabilities

  • Custom model integrations
  • Enterprise AI workflows
  • Specialised inference pipelines
  • AI application integration
  • Business-specific LLM solutions
Technology Ecosystem

Built Around the Open LLM Ecosystem

We work across modern open-weight models, LLM development frameworks, inference engines, vector databases and cloud infrastructure to create solutions aligned with your technical and business requirements.

Open-weight Models

Production-grade foundation models deployable in self-managed environments.

Meta Llama

Foundation & Instruct

Qwen

Multilingual & Coding

Mistral

Dense & MoE Models

Gemma

Compact Open Weights

DeepSeek

Reasoning & Code

Fine-Tuning & Development

Modular training, parameter-efficient adaptation, and evaluation toolchains.

Hugging Face

Model Hub & Tooling

Transformers

Model Architecture Library

PEFT

Parameter-Efficient Tuning

LoRA

Low-Rank Adaptation

QLoRA

Quantised Adaptation

RAG & Orchestration

Composable pipelines for ingestion, retrieval, reranking, and agent workflows.

LangChain

Workflow Orchestration

LlamaIndex

Data & RAG Framework

Haystack

Modular Search Pipelines

Inference & Serving

High-throughput serving engines optimised for GPU and local hardware footprints.

Ollama

Local & Edge Serving

vLLM

PagedAttention Serving

llama.cpp

GGUF & CPU/GPU Runtime

Hugging Face TGI

Text Generation Inference

Vector Databases

Scalable semantic indexing, hybrid filtering, and persistent enterprise memory.

Qdrant

Vector Search Engine

Milvus

Distributed Vector Store

Weaviate

Hybrid Vector Database

Chroma

Lightweight Embeddings DB

pgvector

PostgreSQL Vector Index

Infrastructure

Containerised orchestration and GPU compute platforms across private and cloud estates.

Docker

Container Packaging

Kubernetes

Cluster Orchestration

AWS

VPC & GPU Instances

Microsoft Azure

Private Cloud & AKS

NVIDIA GPU infrastructure

Accelerated Compute

All product names, logos, and trademarks belong to their respective owners and denote open-ecosystem technologies supported in engineering delivery—no official vendor partnership, endorsement, or certification is implied.

Deployment Topologies

Deploy AI Where Your Business Needs It

Architect production LLM workloads around your network security perimeter, residency policies, and compute infrastructure.

CUSTOMER DATA CENTRE PERIMETERInternal LANIAM / ADCorp AppsLLM ControlAPI & GuardrailsLocal Vector DBGPU RackNode 01Node 02NAS Storage
Data Centre Control

On-Premise Infrastructure

Run models within your own data centre with control over infrastructure, networking and deployment.

  • Direct deployment on enterprise GPU servers and bare-metal clusters
  • Full integration with internal Active Directory, VPNs, and local storage
  • Predictable fixed hardware economics without per-token external API fees
DEDICATED SINGLE-TENANT VPC (AWS / AZURE / PRIVATE)PrivateLinkVPN / TLSPrivate KMSManaged Kubernetes GPU ClusterServing PodsvLLM / TGIAutoscaled GPUPrivate DataVector StoreObject Bucket
Isolated VPC Topology

Private Cloud

Deploy dedicated LLM environments within your preferred cloud infrastructure.

  • Single-tenant VPC isolation with private endpoints and zero public exposure
  • Kubernetes-managed GPU scaling aligned to workload demand windows
  • Region-pinned storage and inference respecting data residency mandates
AIR-GAPPED ENCLAVE (ZERO EGRESS)Offline BundlePinned WeightsLocal RegistrySBOM VerifiedLocal RuntimeLocal GuardrailsOffline TelemetryPublicInternetBLOCKED
Zero External Egress

Air-Gapped Environments

Support isolated environments where network connectivity and external dependencies must be restricted.

  • Pre-bundled offline container images, model weights, and private registries
  • Localised evaluation, observability, and guardrail execution without internet calls
  • Designed for sensitive defence, industrial OT, and regulated operational networks
Engagement Models

Flexible Engineering Engagements. Long-Term Technology Partnerships.

Engage Dream Filler for focused advisory assessments, individual implementation projects, or ongoing lifecycle engineering and managed support.

Individual Projects & Architecture Discovery (01–02)Embedded Teams & Ongoing Support Partnerships (03–05)
01
Project / Advisory

LLM Consulting & Architecture Assessment

Advisory & Architecture Blueprint

Structured technical discovery covering use-case feasibility, open-weight model benchmarking, infrastructure sizing, security boundaries, and total architecture design before major capital commitment.

Business Use Case

Ideal for technology leaders planning a private LLM roadmap, validating build-vs-buy economics, or preparing an executive technical blueprint.

Advisory
02
Project Delivery

End-to-End LLM Implementation

Scoped Project Delivery

Scoped delivery of production-ready LLM capabilities—spanning fine-tuning, enterprise RAG pipelines, private inference setup, MCP/API gateways, guardrails, and application integration.

Business Use Case

Ideal for organisations with defined business workflows ready to build and deploy a private knowledge assistant, extraction pipeline, or agentic workflow.

Implementation
03
Embedded Team

Dedicated LLM Engineering Resources

Embedded Engineering Capacity

Embed specialised LLM, MLOps, and full-stack integration engineers alongside your internal product and platform teams to accelerate multi-quarter AI initiatives.

Business Use Case

Ideal for engineering organisations building internal AI platforms or multiple business-unit copilots that require sustained engineering velocity.

Dedicated Engineering
04
Ongoing Support

LLM Support & Maintenance

Ongoing Maintenance & Support

Ongoing technical support, incident troubleshooting, runtime updates, evaluation regression monitoring, and stability maintenance for existing open-weight LLM deployments.

Business Use Case

Ideal for enterprises running LLMs in production that need dependable engineering stewardship, version governance, and structured escalation support.

Support
05
Lifecycle Operations

Managed LLM Operations

Managed Platform Operations

Comprehensive operational stewardship covering model lifecycle management, continuous evaluation, guardrail tuning, capacity planning, and controlled model migrations.

Business Use Case

Ideal for enterprises operating business-critical LLM infrastructure that prefer a dedicated partner overseeing day-to-day operational health and evolution.

Managed Operations
Strategic Engineering Collaboration

Enterprise LLM Engineering, Powered by LLM-MONK

Combining engineering execution with specialised LLM expertise.

Dream Filler brings end-to-end product engineering, software development, cloud infrastructure and enterprise integration capabilities. Through our collaboration with LLM-MONK, we aim to provide specialised open-source LLM engineering, model optimisation, deployment and lifecycle support for enterprise environments.

Dream Filler Logo

Dream Filler

Enterprise Engineering & Delivery Partner

Full-stack software delivery, cloud infrastructure, IoT systems, and long-term enterprise application integration.

  • Product engineering
  • Software development
  • Cloud and infrastructure
  • Enterprise integrations
  • Application development
  • Ongoing technical support
Application, Cloud & Enterprise Systems Execution
Dream Filler Logo×
Unified Delivery

Unified Enterprise LLM Delivery Ecosystem

Combining Dream Filler’s software, cloud, and system integration execution with specialised open-source LLM engineering.

Single accountable delivery workflow
Production-grade governance & continuity
Powered by LLM-MONK

LLM-MONK

Specialised Open-Source LLM Engineering

Dedicated technical depth across open-weight model customisation, inference efficiency, RAG architectures, and production LLM lifecycles.

  • LLM engineering expertise
  • Model optimisation
  • Fine-tuning and RAG
  • Model evaluation
  • LLM lifecycle expertise
Model Adaptation, Optimisation & Lifecycle Depth
Platform Visibility

Engineering & Operations Dashboards Built for Control

Purpose-built telemetry consoles give engineering and operations teams clear visibility across fine-tuning pipelines, model serving health, risk signals, and multi-model usage governance.
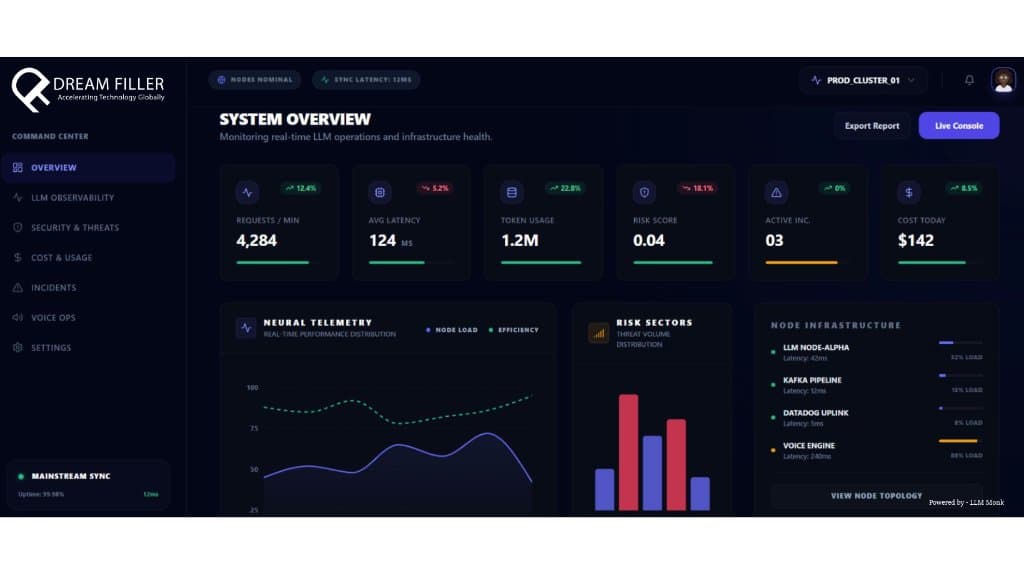
Dream Filler Enterprise LLM Operations Command Center dashboard powered by LLM-MONK
Observability & Security

Enterprise LLM Operations Command Center

Unified operational view spanning request throughput, latency telemetry, risk monitoring, incident tracking, and node infrastructure health.

01 / 03
Why Dream Filler

Beyond AI Implementation. Engineering for the Long Run.

Enterprise LLM deployments rarely succeed as standalone model endpoints—they depend on dependable software architecture, secure cloud or on-premise infrastructure, and clean integration with existing systems of record.

Our LLM practice builds directly on Dream Filler’s broader experience across IoT ecosystems, cloud platforms, custom software development, operational automation, and enterprise product engineering.

Connected Engineering Foundations

IoT & Edge TelemetryCloud & Data InfrastructureCustom Software EngineeringWorkflow AutomationEnterprise Product Delivery
Full-Stack Delivery

End-to-end engineering capabilities

From architecture discovery and backend APIs to web/mobile user interfaces, we deliver complete working systems rather than isolated notebooks.

Open Ecosystem

Open-source and open-weight model expertise

Deep familiarity across modern open-weight families, inference runtimes, and adapter workflows so your stack stays transparent and portable.

Infrastructure Agnostic

Flexible infrastructure deployment

Proven engineering discipline across AWS, Azure, private clouds, on-premise data centres, and constrained or isolated network environments.

Enterprise Systems

Integration with existing enterprise applications

Built upon Dream Filler’s track record in custom enterprise software, IoT telemetry platforms, cloud backends, and operational automation.

Engineering Alignment

Dedicated technical resources

Work directly with specialised engineering teams across software, DevOps, and LLM lifecycles with clear communication and accountability.

Lifecycle Stewardship

Long-term support and maintenance

Sustained post-launch engineering covering monitoring, regression evaluation, model upgrades, and modernisation as your needs evolve.

Start the Conversation

Have an LLM Initiative? Let’s Engineer It Together.

Whether you’re planning your first private LLM deployment, looking to optimise an existing AI environment or searching for a reliable engineering partner to maintain your production LLM infrastructure, Dream Filler can help.

Engineering Consultation

Request an LLM Consultation

Share your infrastructure context, target use cases, and lifecycle needs. Our engineering specialists will align with your team on architecture options and practical next steps.

Contact Information

Speak directly with Dream Filler’s enterprise engineering team.

How We Engage

  1. 1Architecture & Environment Review: Align on data boundaries, security posture, and hosting constraints.
  2. 2Model & Lifecycle Scoping: Identify evaluation criteria, fine-tuning or RAG scope, and support model.
  3. 3Actionable Delivery Proposal: Receive a tailored engineering plan covering build, integration, or ongoing support.
Dream Filler Logo×Powered by LLM-MONK

Enquiries are handled confidentially by Dream Filler’s enterprise engineering team.